POPE
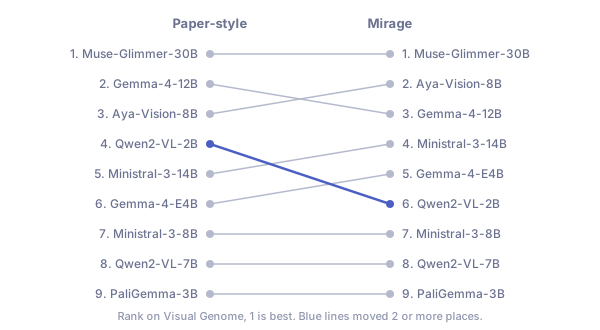
Visual Genome “no” questions pick their object from 82,827 free text names. Of the 1,500 “no” questions, 301 were junk names like “stillness” and “flloor”, 101 named objects that were in the image, and 15 could not be checked from the image.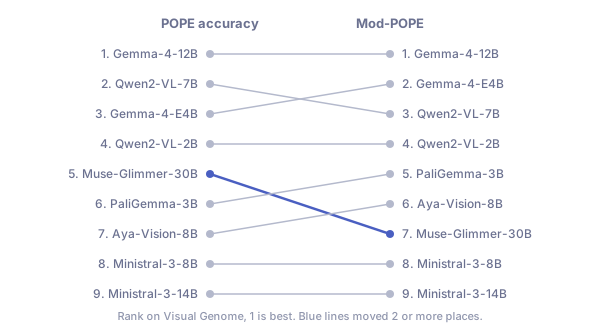
ROPE
Only 214 of 2,500 Visual Genome boxes hold a single object, so a box labelled “road” with a car on it graded the answer “car” as wrong. The old answer parser also cut “piece of cake” to “piece”. For Gemma-4-12B, fixing the parser alone moved ROPE from 21.4 to 35.6, and the judge moved it to 65.5.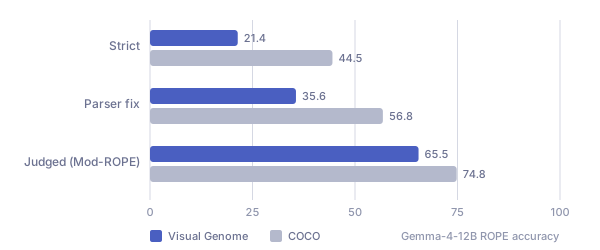
CHAIR
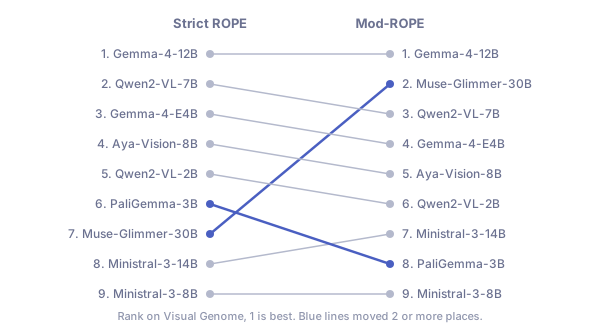
PaliGemma ranked first on raw CHAIR-I because 115 of its 500 captions were under 5 words, such as “kitchen”. Sparse labels also counted visible objects like “sky” as hallucinations: in a 50 image check, Gemma-4-12B had 401 flagged words with no matching label, and 228 were visible objects, 165 were not objects at all, and 8 were truly absent.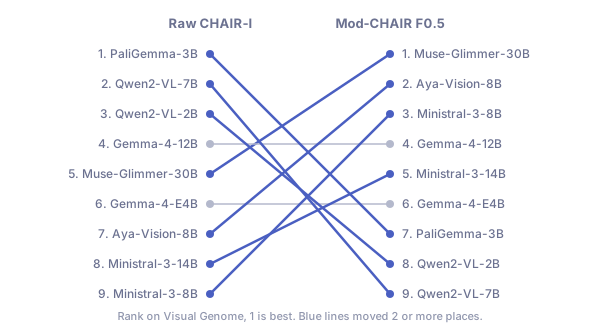
THRONE
The evaluator credited about 30 categories per image to PaliGemma’s one to three word captions, and the caption “yes” got 196 objects. The paper-style column already uses class-wise F0.5. Mirage adds the 5 word minimum and the judge-completed labels.